15 · Next Action Planning
Next action planning uses current observations and historical context to predict the subsequent surgical action, modeling transitions in the workflow.
Input and output: Observed action context → the next action's category or a short description.
Source data and labels: Temporally ordered action clips, each with a class and start/end times: A1 → A2 → A3.
Construction method: Use the current clip and preceding context as input, and the immediately following clip's label as the target. In the diagram, A1 and A2 form the observed context; A3 supplies the answer, without its footage entering the input.
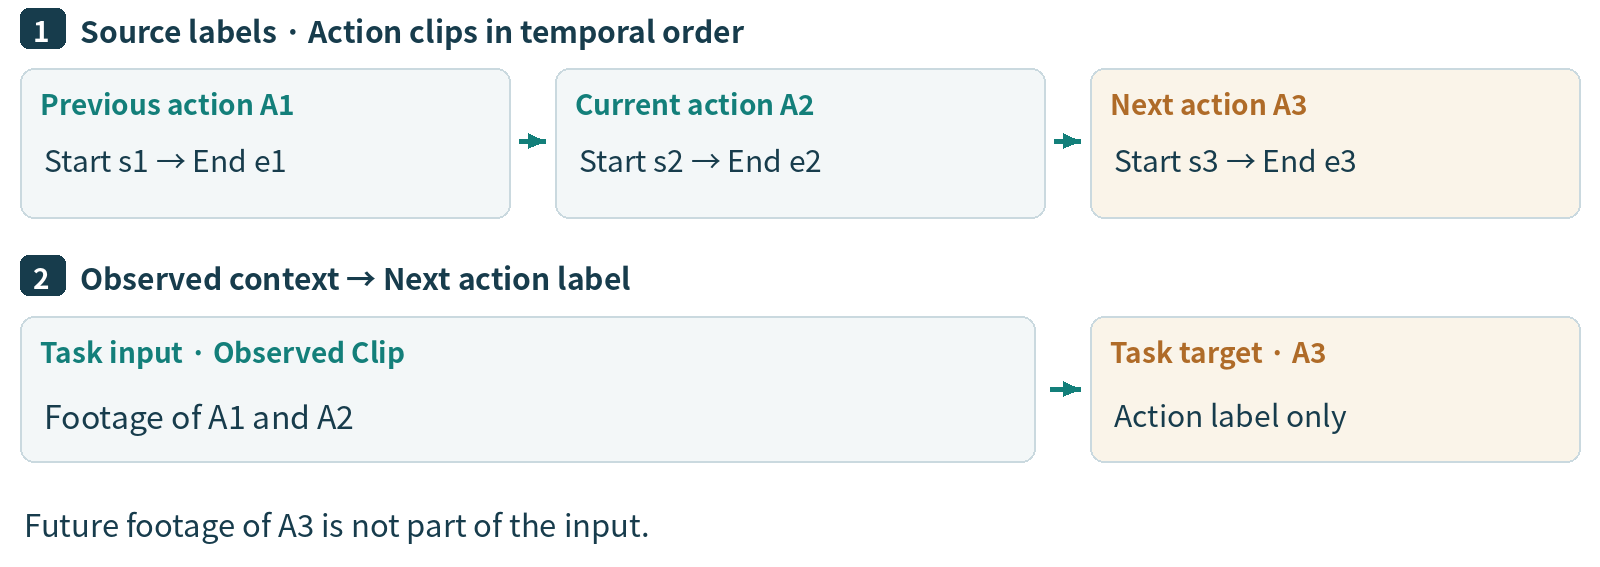
Figure 5. The next clip's action label supplies supervision for the observed context.
Q: Based on the observed clip, which action comes next?
A: A3, the action label immediately following the current clip A2.